Menu Close
AI & LegalTech Automation Platform

Built A Global Legal AI Assistant Using LLM & Web Scraping – Powering Legal Intelligence Across 120+ Countries

By building a LegalTech AI platform powered by LLMs and large-scale web scraping, Shrijan Tech helped automate legal data extraction from 120+ government bodies and trained a custom AI assistant to deliver real-time legal summaries and compliance insights across 25+ legal categories.

Case Study

Overview

True transformation begins with commitment a willingness to take on complexity, understand the price of innovation, and persist until excellence is achieved.

Our client, a forward-thinking LegalTech startup, had a vision to make global law accessible to everyone from corporate counsels to compliance officers. Yet, the challenge was immense: legal data scattered across 120+ government bodies, written in different formats and languages, and locked behind outdated systems. Shrijan Tech partnered with them to turn this ambition into reality. Through large-scale data scraping, domain-specific LLM training, and intelligent AI automation, we built a global Legal AI assistant capable of reading, summarizing, and comparing laws across borders. This project wasn’t just a technological achievement it was a statement of persistence, precision, and the belief that access to legal knowledge should have no boundaries.
LegalTech AI Startup

Business

Europe

Location

Key Challenges

Unstructured Global Legal Data

Legal information was dispersed across 120+ government websites, PDFs, and scanned documents inconsistent in format and language.

Unoptimized UI

Manual extraction was impossible at scale, requiring automation to crawl and standardize thousands of legal records daily.

Contextual Understanding for AI

Generic LLMs failed to interpret complex legal language, leading to inaccuracies in summaries and jurisdiction-based comparisons.

Orphaned Pages

End users lawyers, compliance officers, and enterprises needed quick, accurate answers, not lengthy documents or raw data.

Solutions Provided

Automated Legal Data Extraction System

Developed Python-based web scrapers capable of collecting and parsing structured and unstructured legal data from 120+ official government portals worldwide.

Advanced OCR & Classification Pipeline

Implemented OCR and text-classification pipelines to digitize scanned PDFs, tagging and categorizing data under 25+ legal domains such as corporate law, IP, and compliance.

Custom Legal LLM Development

Trained a domain-specific Legal Large Language Model using proprietary data, enhancing context retention, accuracy, and multilingual understanding.

Intelligent Legal Chatbot

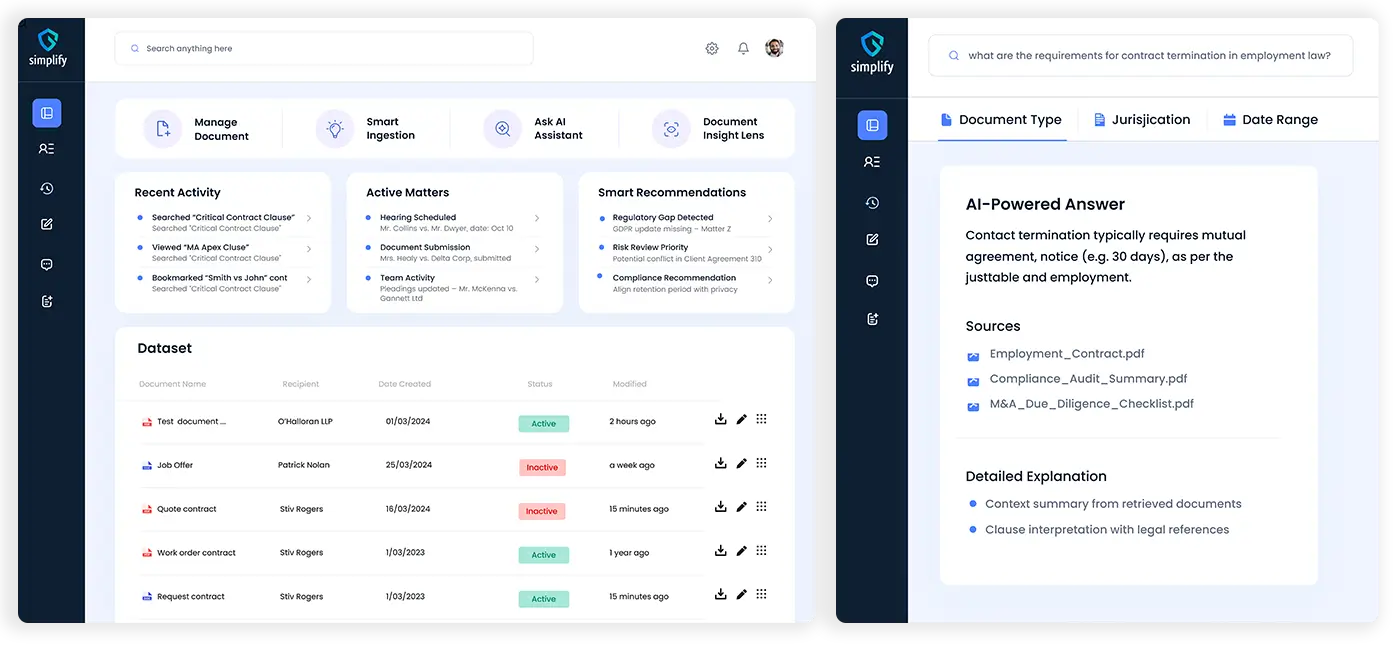
Integrated an AI chatbot powered by LangChain and OpenAI APIs, allowing users to query, summarize, and compare laws across jurisdictions in real time.

Knowledge Graph & Vector Search

Built a knowledge layer using Elasticsearch and Pinecone for semantic search, enabling contextual retrieval and verified legal citations.

Scalable Cloud Architecture

Deployed the system on AWS using Lambda, EC2, and Docker for auto-scaling, ensuring high performance even with millions of records.

Technology Stack

WordPress
Python
JavaScript
React
HTML
PHP
CSS
FastAPI
Next.js
LangChain
Open AI
HuggingFace Transformers
PostgreSQL
Elasticsearch
AWS
Docker
Kubernetes

Key Results

120+ Countries Integrated
Successfully scraped and structured legal data from 120+ government bodies and repositories in multiple languages.
25+ Legal Categories Indexed
Organized data into 25+ specialized domains, enabling category-specific legal searches and summaries.
99% Automation Accuracy
Achieved high accuracy in document extraction, classification, and metadata tagging through OCR and NLP pipelines.
80% Faster Legal Responses
The AI chatbot reduced legal research time drastically by delivering verified summaries within seconds.
1.2M+ Legal Docs Processed
Ingested and structured over 1.2 million legal records into a searchable knowledge base within three months of deployment.